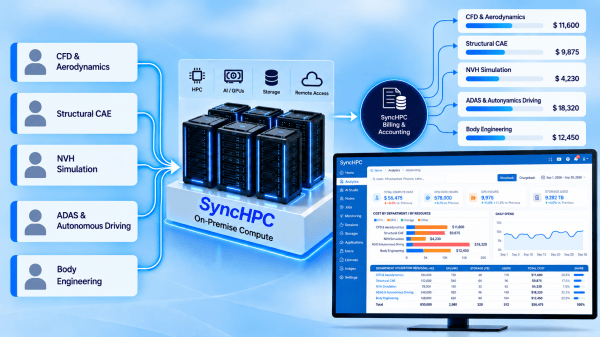
The GPU is busy. The cluster is busy. The queue is busy. But who is actually consuming the compute, and what is that consumption costing the organization? That question gets harder when one infrastructure serves HPC simulations, AI workloads, remote engineering labs, VDI, and containerized applications. A single GPU may run a Slurm job overnight,... Continue Reading →
Slurm on Kubernetes: What Slinky Solves and How SyncHPC Makes It Enterprise-Ready
The real challenge isn't Slurm vs. Kubernetes Ask most infrastructure teams about HPC and AI convergence and the conversation turns into a scheduler debate. That framing misses the point. In practice, the choice was made years ago by the users. Simulation teams built their workflows on Slurm because it delivers what tightly coupled computing demands:... Continue Reading →
Building a Scalable AI Lab with SyncHPC: A Real-World Deployment at an Educational Institute
Setting up an AI lab for "scalability" needs a thorough process and right tools. This blog describes the implementation of "scalable" AI solution using SyncHPC. Here’s how a leading education institute partnered with Syncious to build a high-performing and scalable AI Lab Using the SyncHPC platform empowering research students with real-world AI and machine learning... Continue Reading →