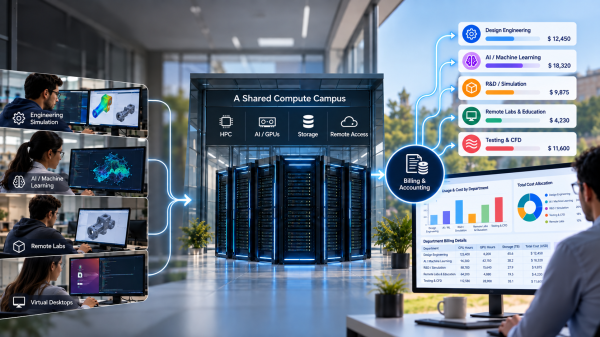
The GPU is busy. The cluster is busy. The queue is busy. But who is actually consuming the compute, and what is that consumption costing the organization? That question gets harder when one infrastructure serves HPC simulations, AI workloads, remote engineering labs, VDI, and containerized applications. A single GPU may run a Slurm job overnight,... Continue Reading →
The Rise of Compute-Oriented Campuses: HPC + AI + Remote Labs & Why Chargeback Is Becoming Essential ?